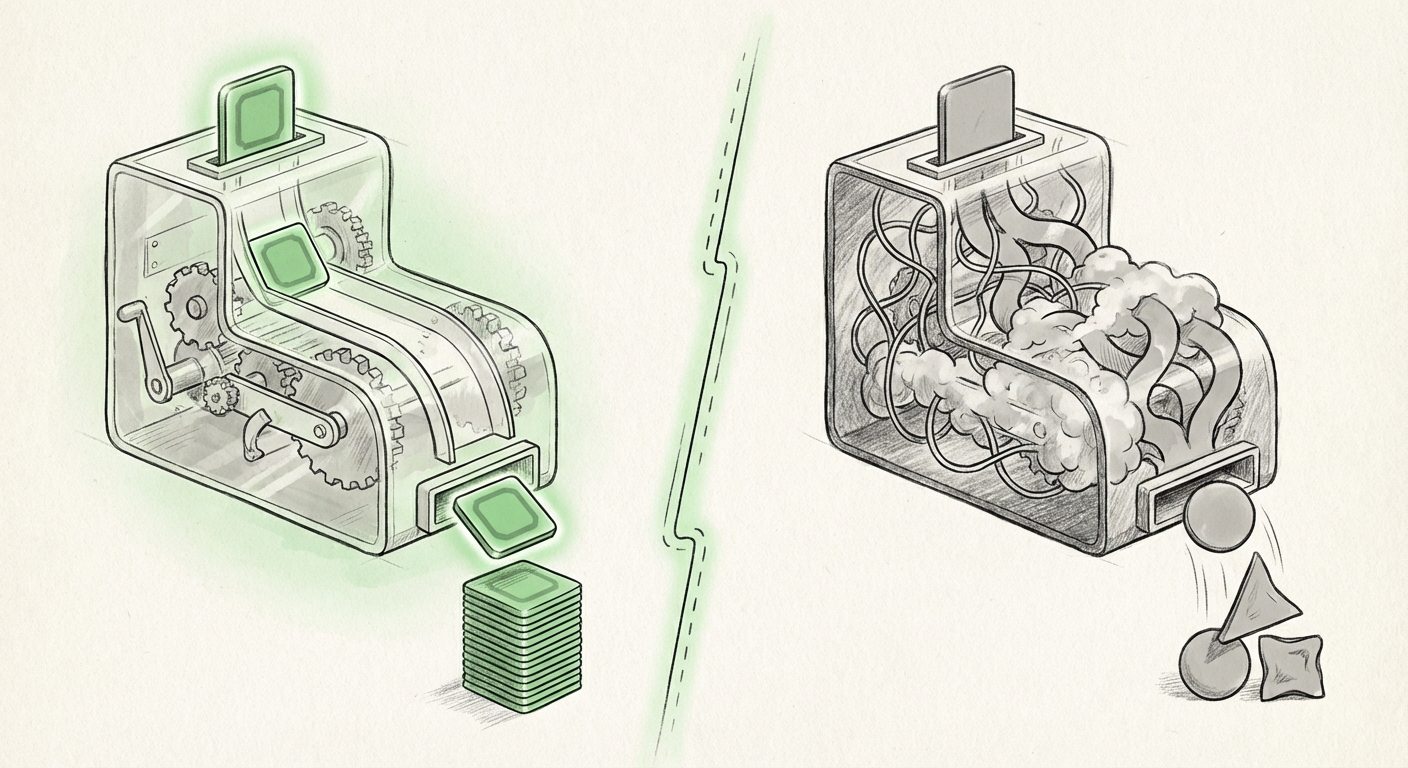
When the AI Model You Need Doesn't Exist, You Build It Yourself
For the past few years, the story of artificial intelligence has been a story about giant models built by a handful of giant labs. You waited for the next release. You tested it. You complained about it. Then you waited again. Companies picked a model the way you pick a phone plan, choose from the options on the shelf, accept the terms, hope it mostly works.
That era is ending. A new pattern is taking hold, and it's simple to describe: if the model you need doesn't exist, you make it yourself. Not because you're a research lab. Because you're a business, a hospital, a law firm, a game studio, or a two-person startup with a very specific problem that no general-purpose model was ever designed to solve.
The Disappointment Phase of Off-the-Shelf AI
The first wave of AI adoption ran on a simple promise: one very large model could do everything. Write your emails. Summarize your meetings. Answer your customers. Build your app. That promise was real, and it delivered a lot of value.
But it also ran into a wall that every team eventually hits. General models are trained to be good at everything, which means they are rarely excellent at anything specific. They don't know your internal jargon. They don't understand your product catalog. They don't follow your compliance rules unless you remind them again and again. They can be confidently wrong about details that matter enormously in your world.
Worse, the big general models keep changing underneath you. A prompt that worked last quarter starts behaving differently. A capability you depended on gets tuned down. You don't own the model. You're renting it, and the landlord can repaint whenever they like.
This is where frustration turns into engineering. Teams start asking a different question. Not "which model should we use?" but "why are we using someone else's model at all?"
Why Building Your Own Suddenly Became Possible
Three things had to line up before DIY models could become normal, and all three have now happened.
1. Strong open-weight foundations exist
You no longer have to train a model from zero, which would cost more than most companies earn in a decade. Powerful open-weight models are available to download, run on your own hardware, and modify. That changes the math completely. You're not building a house from raw timber. You're renovating a house that already has plumbing.
2. Fine-tuning got cheap and approachable
Customization used to require a research team. Today, a skilled engineer can take an open foundation model and teach it your domain using far less data and compute than before. Adapter techniques let you bolt new skills onto a model without rewriting the whole thing. You can train on a few thousand carefully chosen examples instead of billions of documents.
3. Small models got genuinely good
There's a quiet revolution in compact models. A smaller, sharply focused model can often beat a much larger general one at a narrow task, sorting support tickets, reading invoices, flagging contract clauses, labeling medical notes. It runs faster, costs less per request, and can often live on your own servers.
Put those three together and the barrier to entry collapses. The question shifts from can we build this? to should we?
The Rise of the Single-Purpose Model
We are moving into an age of specialized AI. Instead of one giant brain, you get a workshop of small tools, each built for one job and very good at it.
Think about how software already works. You don't run one giant program that does accounting, design, payroll, and email. You run many tools that each do one thing well. AI is heading the same direction. The future isn't one model to rule them all. It's a fleet of purpose-built models working together, with a general model acting as the coordinator on top.
This is a big shift in how AI gets purchased and used. Value moves away from "access to the biggest model" and toward "the best model for my exact problem." That's a much friendlier world for smaller players, because domain knowledge, not raw compute, becomes the advantage.
What This Means for the Future of AI
Moats move from models to data
When everyone can download a strong foundation model, the model itself stops being a differentiator. What can't be copied is your data: your customer conversations, your internal documents, your expert decisions, your labeled examples. Companies that have been quietly hoarding and organizing that data suddenly find themselves holding the most valuable asset in the room.
The winners will be evaluators, not just builders
Building a custom model is the easy part now. Knowing whether it's actually good is the hard part. The teams that thrive will be the ones with solid testing, real evaluation sets, clear success metrics, and a habit of checking their model against reality instead of vibes. Training is cheap. Trust is expensive.
AI becomes infrastructure, not a product
As custom models multiply, they'll fade into the background the way databases did. Nobody brags about their database. It just works. The same will happen with task-specific models. The interesting question won't be which model are you using? It'll be what are you doing with it?
Practical Implications for Businesses
The cost story flips
Big general models charge by the token, and those costs scale with usage. A specialized small model you host yourself has a different cost curve. You pay upfront to build and host it, then run it cheaply forever. For high-volume, repetitive tasks, that math can be dramatic. For rare, complex, creative tasks, the big general model still wins. Smart teams will use both, routing each request to the right tool.
Privacy and control become real options
Some industries simply cannot send sensitive data to an outside service. Legal, healthcare, finance, government, defense. Custom models that run inside your own walls solve a problem that no amount of policy language could solve before. This alone will drive adoption in regulated sectors.
Vendor risk drops
When your critical workflow depends on a model someone else controls, you carry hidden risk. Pricing changes, deprecations, policy shifts, outages. Owning a model, or at least owning a fine-tuned version of an open one, gives you a fallback. Dependency is comfortable until it isn't.
Small teams get leverage
A three-person team with deep domain knowledge and a clean dataset can now build something that outperforms a much larger competitor's generic AI feature. Expertise plus a focused model is a genuinely new kind of competitive weapon.
A Practical Playbook
If you're thinking about building your own model, here's a sensible path.
- Start with the task, not the model. Write down one specific job in one sentence. "Classify incoming support emails by urgency and product line." If you can't describe it that tightly, you're not ready to build.
- Measure the baseline first. Test how a general model does on that exact task today. You need a real score to beat, or you'll never know if your custom model helped.
- Collect and clean examples. A few thousand high-quality labeled examples beat a million messy ones. Quality of labels is usually the whole ballgame.
- Try the cheapest option first. Better prompting, retrieval over your own documents, or a small fine-tune. Climb the ladder one rung at a time.
- Build a real evaluation set. Hold back examples your model never trains on. Test on those. This is non-negotiable.
- Ship it behind a router. Let a general model handle the weird, rare requests and hand the common ones to your specialist.
- Watch it in production. Track accuracy, cost, and speed. Retrain when the world changes, because it will.
The Hard Truths Nobody Mentions
Custom models are not a free lunch, and pretending otherwise leads to expensive disappointment.
Data quality is the bottleneck. Most failed projects don't fail because of the model. They fail because the training data was messy, biased, or just wrong. Garbage in, confidently wrong out.
Maintenance is forever. A model is not a one-time purchase. The world shifts, language shifts, your business shifts. Something you build and forget will quietly rot.
You can build the wrong thing beautifully. A perfectly trained model for a task nobody actually needed is still a waste. Solve a real, painful, repeated problem.
Safety doesn't disappear. A custom model is still a model. It can still produce harmful, biased, or leaking output. Guardrails and review matter just as much as they do with a hosted service.
The Bigger Picture
The most important thing about the DIY model trend isn't the technology. It's what it does to power.
For a while, it looked like AI would concentrate into a few enormous systems owned by a few enormous companies, and everyone else would rent access. That's still part of the picture, and those frontier models will keep pushing the edge of what's possible.
But underneath that, something more distributed is growing. Thousands of specialized models, each tuned to a narrow slice of the world, each owned by the people who understand that slice best. Doctors building models that read their specialty's notes. Manufacturers building models that spot defects in their specific line. Local governments building models that answer questions in the languages their residents actually speak.
That's a healthier future than one where everyone queues up for the same giant model. It spreads capability. It rewards expertise. It gives small players a real seat at the table.
And it started with a very ordinary feeling: the model you needed didn't exist, so you made it yourself.
If that sounds like your situation, the tools are already on the table. The question is whether you start building.