MoPrO-SD Explained: How Modular Prompt Optimization Is Fixing AI's Blind Spot in Stance Detection
Every minute, millions of people post opinions online. They praise a brand. They attack a policy. They mock a product launch. And somewhere behind the scenes, an AI system has to answer one deceptively simple question: is this person for it, against it, or somewhere in between?
That job is called stance detection, and it is one of the hardest everyday tasks in natural language processing. It is also one of the most commercially valuable. A company that can tell the difference between "I love how bold this ad is" and "wow, bold move, genius", the second is sarcasm, holds a real advantage over one that cannot.
A new piece of research published on October 12, 2026, titled MoPrO-SD: Modular Prompt Optimization for Stance Detection, points at a bigger shift in how AI systems get built. The headline idea is not "train a bigger model." It is: break the instructions into pieces, optimize each piece, then recombine them. That sounds modest. It is not. It signals where reliable AI is heading, away from giant monolithic prompts and toward modular, testable, reusable components.
What Stance Detection Actually Is, and Why It's So Hard
Stance detection asks a model to look at a piece of text and decide where the writer stands on a specific target. The target could be a brand, a politician, a law, a technology, or an idea. The usual answers are in favor, against, or neutral (sometimes with a fourth "mixed" or "unclear" label).
It sounds like sentiment analysis, but it is not the same thing. Sentiment asks: is this text positive or negative? Stance asks: positive or negative toward what? A message can be glowing about one topic while tearing down another in the same sentence. It can criticize a person while supporting their cause. Sentiment alone misses all of that.
Several things make stance detection genuinely difficult:
- Sarcasm and irony. The literal words point one way and the meaning points the other.
- Missing context. Social posts are short. The target is often implied, not named.
- Evolving slang. Language shifts fast, and last year's examples become this year's confusion.
- Multilingual and cultural variation. The same phrasing can signal support in one community and rejection in another.
- Mixed feelings. Real people are rarely fully for or fully against anything.
For businesses, the stakes are practical. Brand teams want to know whether people are defending the company or piling on. Policy teams want to know whether criticism is a genuine safety concern or routine frustration. Getting that wrong in either direction has real costs.
The Problem With One Giant Prompt
For several years, the standard way to make a language model do a specialised job was to write one long instruction. You would define the task, add rules, paste in examples, describe the output format, and hope the model followed along.
This approach has an obvious weakness: it is fragile. Everything is tangled together. Change one line to fix an edge case and you might break behaviour on a dozen other cases. Long prompts also get slower and more expensive on every single request, because the model has to re-read the whole block each time.
Worse, the prompt becomes impossible to reuse. A prompt tuned for analysing product reviews may fail completely on political posts. A prompt tuned for English may collapse on Spanish. Teams end up copy-pasting variations and losing track of which version works and why.
What MoPrO-SD Changes, Modular by Design
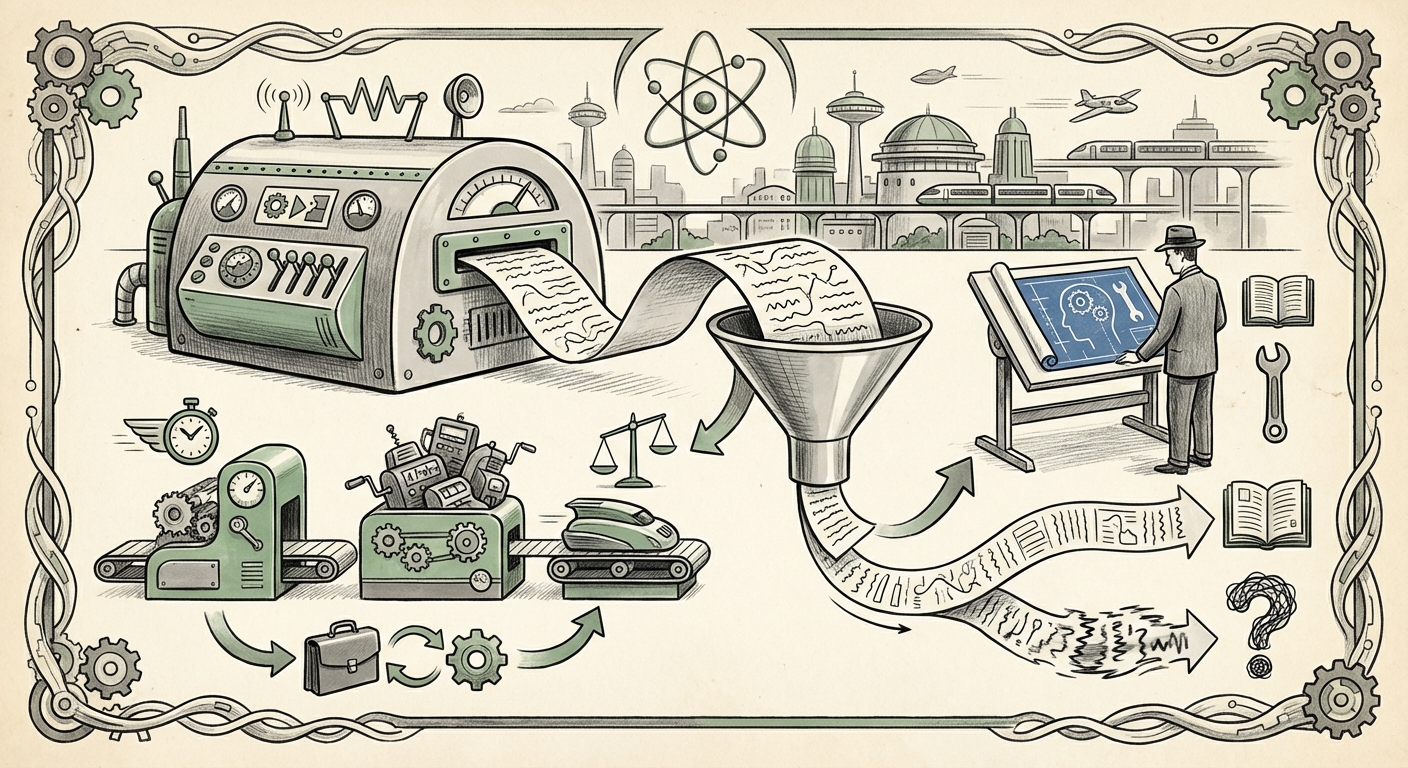
The title tells the story. Modular Prompt Optimization means treating a prompt not as one block of text, but as a set of separate modules, each with a single job. In stance detection, those modules might cover the definition of the task, the list of allowed output labels, the formatting rules, a handful of tricky examples, and domain-specific context about the target being discussed.
Each module is then improved on its own, and the improved pieces are recombined into a full working system. Think of the difference between a race car built with interchangeable parts and one welded together as a single lump of metal. When it rains, you swap the tyres. You do not rebuild the engine.
That design carries several concrete advantages:
- Reuse. A well-tuned formatting module works across dozens of different tasks.
- Cheaper improvement. If the weak link is the examples module, you fix that, you do not re-tune everything else.
- Easier debugging. When the system fails, you can trace which module caused the failure.
- Better transfer. Moving from one topic or language to another becomes a matter of adapting one module instead of rebuilding from scratch.
- Transparency. A human reviewer can read each module and see exactly what instruction it is giving the model.
There is also a cost angle. Narrow, well-specified modules can often be handled by smaller, faster, cheaper models. You do not always need the largest available system when the instruction has been broken down properly. That matters a great deal for anyone running high-volume analysis.
Why This Is a Signal About the Future of AI
MoPrO-SD is one paper, but it sits on top of three trends that are reshaping how AI gets deployed.
1. Prompting Is Becoming Engineering
Prompt writing started as an art. It is turning into a discipline with versioning, testing, and measurable performance. Once you break a prompt into modules, you can measure each one. That is the moment prompt work stops being guesswork and starts being something you can manage like software.
2. Composition Beats Raw Scale
For years the answer to every AI problem was "use a bigger model." That is getting expensive and, in many cases, unnecessary. A mid-sized model with a precisely engineered, modular instruction set can outperform a much larger model given a vague one-liner. Modular prompt design is how that advantage gets captured reliably.
3. Evaluation Becomes the Real Bottleneck
If you can optimize modules, you need a way to know whether a change made things better. That pushes teams toward building proper test sets and scoring methods. In the next phase of AI, the organisations that win will not be the ones with the fanciest model access. They will be the ones with the best evaluation data.
4. It Maps Onto Agentic Systems
AI agents, systems that plan, use tools, and act over multiple steps, depend on instructions that hold up under pressure. Modular instructions make agent behaviour more predictable, because each role and rule is isolated and checkable rather than buried in a wall of text.
What It Means for Businesses
The practical implications land quickly once you look at where stance detection shows up.
- Social listening and brand monitoring. Separating "people are talking about us" from "people are backing us" is the difference between a vanity metric and a decision.
- Market research. Tracking whether opinion is shifting on a product category, a competitor, or a regulation over time, and across regions.
- Customer support. Sorting genuine hostility from a frustrated superfan changes how a message gets handled.
- Risk and compliance. Spotting coordinated messaging campaigns aimed at a company, a sector, or a public figure.
- Content moderation. Distinguishing fair criticism from harassment, which are very different things with very different responses.
The deeper change is organisational. If prompts become modules, they become assets. They need owners, version histories, and tests. Companies that already treat prompts casually will feel this gap first.
What It Means for Society
Tools that read public opinion at scale are never neutral. Better stance detection can help researchers measure polarisation more honestly, track how false claims spread and who backs them, and give journalists a clearer picture of public sentiment than raw volume counts ever could.
But the same capability cuts the other way. The ability to classify people by their stated views is exactly the capability that enables profiling, targeting, and pressure campaigns. The technology does not decide which use is legitimate. Governance does.
There is one quiet positive here. Modular prompts are more auditable than a single tangled instruction. When rules are separated and documented, outsiders can inspect what a system is actually being told to do. That is a small but real step toward accountability.
There is also a caution. Stance is cultural. A module optimised for one language or community will not automatically work in another. Local validation is not optional, it is the difference between insight and noise.
Actionable Insights: What to Do Now
- Break your prompts into named modules. Task definition, labels, format, examples, and domain context should each be a separate, clearly labelled block.
- Define "correct" before you optimise. Write down what a good answer looks like, then build a small test set you can reuse.
- Version-control prompts like code. Track what changed, when, and what it did to performance.
- Change one module at a time. Isolating changes is the only way to know what actually helped.
- Match model size to the job. Narrow modules often run fine on smaller, cheaper models. Save the heavy lifting for the hard cases.
- Keep humans in the loop on high-stakes calls. Moderation decisions, legal risk, and reputational judgements should not be fully automated.
- Re-validate on a schedule. Language, platforms, and events move. Prompts that worked six months ago may not work today.
- Document the limits. Be explicit about what the system cannot do. That protects you when it fails.
The Hard Parts Nobody Should Skip
Modularity is not magic. The biggest obstacle is evaluation. Without good labelled examples, "optimisation" becomes guesswork with extra steps. And there is a real risk of overfitting, tuning modules so tightly to your test set that they fall apart on real traffic.
Drift is another issue. Slang changes yearly. New events create new targets. Yesterday's examples go stale. Sarcasm, humour, and code-switching between languages remain genuinely hard for current systems, modular or not. And if your example data skews, your modules inherit that skew, modular design does not remove bias, it just makes it easier to locate.
Finally, modularity creates a coordination question. If five teams own five modules, who owns the final system? That is an organisational problem as much as a technical one.
Looking Ahead
The lesson from MoPrO-SD: Modular Prompt Optimization for Stance Detection is bigger than one task. It says that the next wave of AI progress will come as much from careful design as from raw scale. Break the problem into parts. Optimise each part. Measure the result. Recombine.
That approach makes AI systems cheaper to run, easier to fix, and far easier to explain to the people who have to trust them. In a world where AI is increasingly asked to judge what people really mean, that kind of discipline is not a nice-to-have. It is the whole game.
The teams that treat language instructions as engineered products, owned, versioned, tested, will be the ones whose AI systems actually hold up when real users, real sarcasm, and real ambiguity show up.