Do Halting Heads Really Save Compute in Looped Language Models? A Practical Guide to AI Efficiency
AI teams are under pressure to get more thinking out of every dollar spent on compute. One idea getting attention is the looped language model. Instead of running through a fixed stack of layers once, a looped model can reuse parts of its own network to work on a problem longer. That can sound like a path to better reasoning. But it also sounds expensive. If a model can loop many times, what stops it from burning compute on easy questions that did not need the extra work?
That is where halting heads come in. The simple promise is this: a small part of the model learns to decide when to stop looping. Easy inputs stop early. Hard inputs keep going. In theory, the model spends compute only where it helps. In practice, the question is much sharper: do halting heads really save compute, or do they just move the cost around?
This question matters for anyone building, buying, or regulating AI systems. Compute is not just a technical detail. It shapes product cost, response speed, energy use, and who can afford to use advanced AI. The answer to whether halting heads save compute will not come from a slogan. It will come from careful measurement across training, inference, hardware, and real-world workloads.
The Big Idea: Pay for Thinking Only When Needed
A standard language model does a fixed amount of work for every token it produces. A looped model changes that. It can repeat a block of computation, giving the model more internal steps before it answers. This is appealing because some tasks are easy and some are hard. A simple lookup should not need the same effort as a multi-step math problem or a long chain of reasoning.
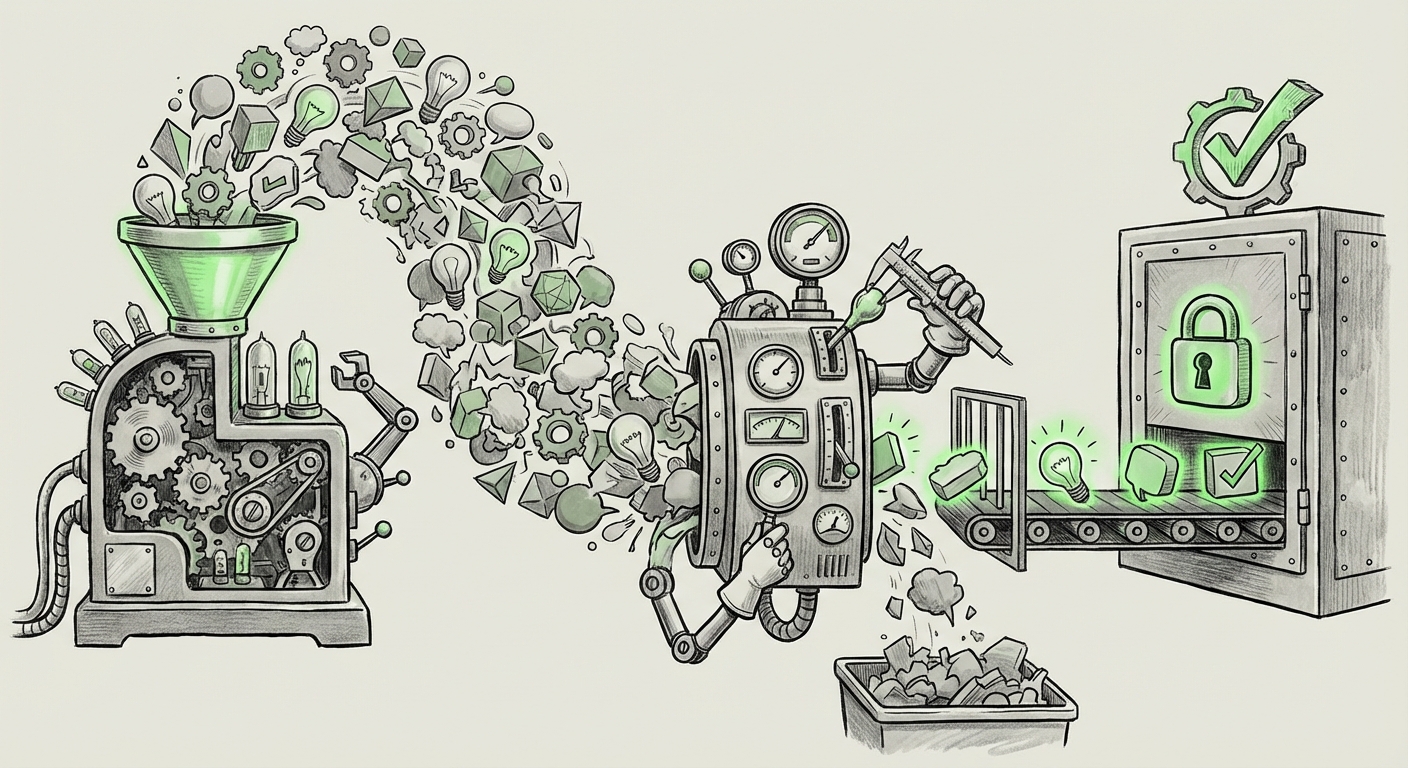
A halting head is meant to act like a brake. It looks at the model’s internal state and predicts whether more looping is useful. If the answer is “we are done,” the model stops. If the answer is “keep going,” it loops again. The dream is adaptive compute: small effort for small tasks, larger effort for larger tasks, all without a human setting a fixed loop count for every case.
On paper, this is a strong idea. Fixed loop counts are blunt. They can waste compute on easy cases and still under-serve hard cases. A learned halt signal promises a better match between effort and difficulty. But the word promise is doing a lot of work. A halting head adds its own computation, its own training cost, and its own failure modes. The savings are real only if the whole system becomes cheaper and no less reliable.
Why Looped Models Need a Brake
Looped models are attractive because they can increase effective depth without making the model physically deeper in the usual sense. They reuse parameters. That can be efficient in memory and model size. But reuse is not free. Every extra loop is more computation at inference time. If a model loops ten times on every request, the cost can climb quickly.
This creates a design tension. More loops can improve the model’s ability to work through hard problems. But more loops also mean more latency and more energy. A model that is very good at hard reasoning but too slow or too costly for normal use is not a practical win. A brake is needed. The halting head is one way to build that brake.
The key test is not whether a halting head can be trained. The key test is whether it saves more compute than it costs, across the mix of requests a real system sees. That mix is important. In a benchmark, most questions may be hard, so looping often makes sense. In a real product, most questions may be easy, so early stopping could save a lot. Or the opposite may happen: a poorly calibrated halt signal may stop too early on hard cases and hurt quality, or loop too long on easy cases and waste money.
What a Halting Head Is Supposed to Do
Think of a halting head as a small decision-maker inside the model. At each loop, it asks: should we continue, or should we answer now? If it says stop, the model exits early. If it says continue, the model takes another loop. The head is trained to make that choice well, usually by learning from examples where extra loops help and where they do not.
This sounds simple, but the decision is subtle. The model does not always know whether another loop will improve its answer. A halt signal can be overconfident. It can stop when the model is wrong. It can also keep looping when the model is stuck. A good halting head must be calibrated. It must know when extra work will change the answer for the better, not just when the model feels finished.
There is also a systems cost. A halting head is another component to train, tune, and monitor. It may need its own data. It may behave differently across languages, tasks, and input lengths. The savings from early stopping must be large enough to cover that overhead. If the head saves a small amount of compute but adds complexity and risk, the net gain may be weak.
The Gap Between FLOPs Saved and Money Saved
One of the biggest traps in AI efficiency is confusing theoretical compute with real cost. A halting head may reduce the number of loops on average. That can reduce the number of floating-point operations, or FLOPs. But cloud bills, latency, and energy use do not always fall in a straight line.
Hardware likes predictable work. If requests stop at different loop counts, the system may struggle to batch them efficiently. Some hardware may sit idle while waiting for longer requests to finish. Memory traffic may not shrink just because compute shrinks. A model that loops fewer times on average can still be slow if the longest requests dominate the queue.
This is why teams need to measure wall-clock time, not just average loop counts. They need to measure cost per request, cost per successful answer, and tail latency. A small group of hard requests can set the user experience for everyone. If halting heads help easy requests but leave hard requests very expensive, the business case may be uneven.
Training cost matters too. A looped model with a halting head may be more complex to train. The savings at inference time may take a long time to pay back the extra training effort. The right question is not “does this save compute in a lab test?” The right question is “does this lower the total cost of ownership for my workload?”
Quality Is the Hidden Cost
Compute savings mean nothing if answer quality drops. A halting head that stops too early can turn a model that would have solved a problem into one that gives a shallow answer. That is a hidden cost. It may show up as lower accuracy, more retries, more human review, or more customer support. Those costs can erase the savings from fewer loops.
This is especially important for tasks where the model needs to reason through several steps. Early stopping may look efficient on average but fail on the exact cases that matter most. A business may save money on simple questions and lose more on the hard ones. The net effect depends on the task mix and the cost of errors.
A strong evaluation should compare a halting-head model against a fixed-loop baseline on the same tasks. It should look at quality, not just cost. It should test edge cases, long inputs, ambiguous questions, and rare languages. It should check whether the halt signal is calibrated: when the model says “stop,” is it actually ready? When it says “continue,” does more looping really help?
What This Means for the Future of AI
The halting-head question is part of a larger shift in AI. The field is moving from “bigger is always better” toward “smarter use of compute.” Adaptive computation is one version of that shift. The goal is not just to build larger models, but to build models that spend effort wisely.
If halting heads work well, they could make advanced AI cheaper to run. That could widen access. Smaller teams could use reasoning-heavy models without huge budgets. Products could respond faster on easy requests and save resources for hard ones. Energy use could fall if fewer loops are needed on average. These are real benefits, but they depend on actual savings, not just the idea of savings.
If halting heads do not deliver, the risk is wasted effort. Teams may add complexity for little gain. Vendors may market adaptive compute as a cure-all. Buyers may plan budgets around savings that do not appear in production. The result could be slower adoption and more skepticism about efficiency claims.
For society, the stakes are about access and trust. Cheaper inference can make AI more available for education, health, and small business. But if cost savings are overstated, the benefits may not reach the people who need them. Reliable efficiency claims also matter for energy planning. Data centers are under pressure to use power wisely. A technique that truly cuts compute can help. A technique that only shifts compute around does not.
Practical Steps for Teams
For leaders and engineers, the halting-head question should be treated as a measurement problem, not a belief system. Here is a practical path:
- Set a clear baseline. Compare against a fixed-loop model and a standard non-looped model. Use the same hardware and the same task mix.
- Measure end-to-end cost. Include training, inference, memory, batching, and retries. Do not stop at average loop count.
- Track tail latency. Look at the slowest requests, not just the average. Hard cases often set the real user experience.
- Test quality by task type. Check easy, medium, and hard cases separately. A single average score can hide failures.
- Check calibration. Ask whether the halt signal knows when more loops will help. Measure false stops and unnecessary loops.
- Run a production-like pilot. Use real traffic, real batch sizes, and real cost data before making a commitment.
- Plan for a range of outcomes. Treat savings as a possible range, not a guaranteed number. Build the business case around the low end.
These steps are not glamorous, but they are how teams avoid buying into a demo that does not survive contact with real workloads. The same discipline applies to any adaptive compute method. The question is always the same: does the system deliver better outcomes per dollar, per second, and per unit of energy?
Conclusion: The Answer Is in the Workload
Do halting heads really save compute in looped language models? The honest answer is that it depends on the whole system. A halting head can reduce unnecessary loops. It can make effort match difficulty. That is a meaningful idea. But savings are not automatic. The head adds overhead. Early stopping can hurt quality. Hardware effects can eat into gains. Training costs can delay payback.
The future of AI will be shaped by these kinds of efficiency questions. The winners will not be the teams that adopt every clever mechanism first. They will be the teams that measure carefully, test on real workloads, and demand evidence before scaling. Halting heads may become a useful tool in that effort. But they should be judged by a simple standard: do they make the system cheaper, faster, or better in ways that users and businesses can actually see?