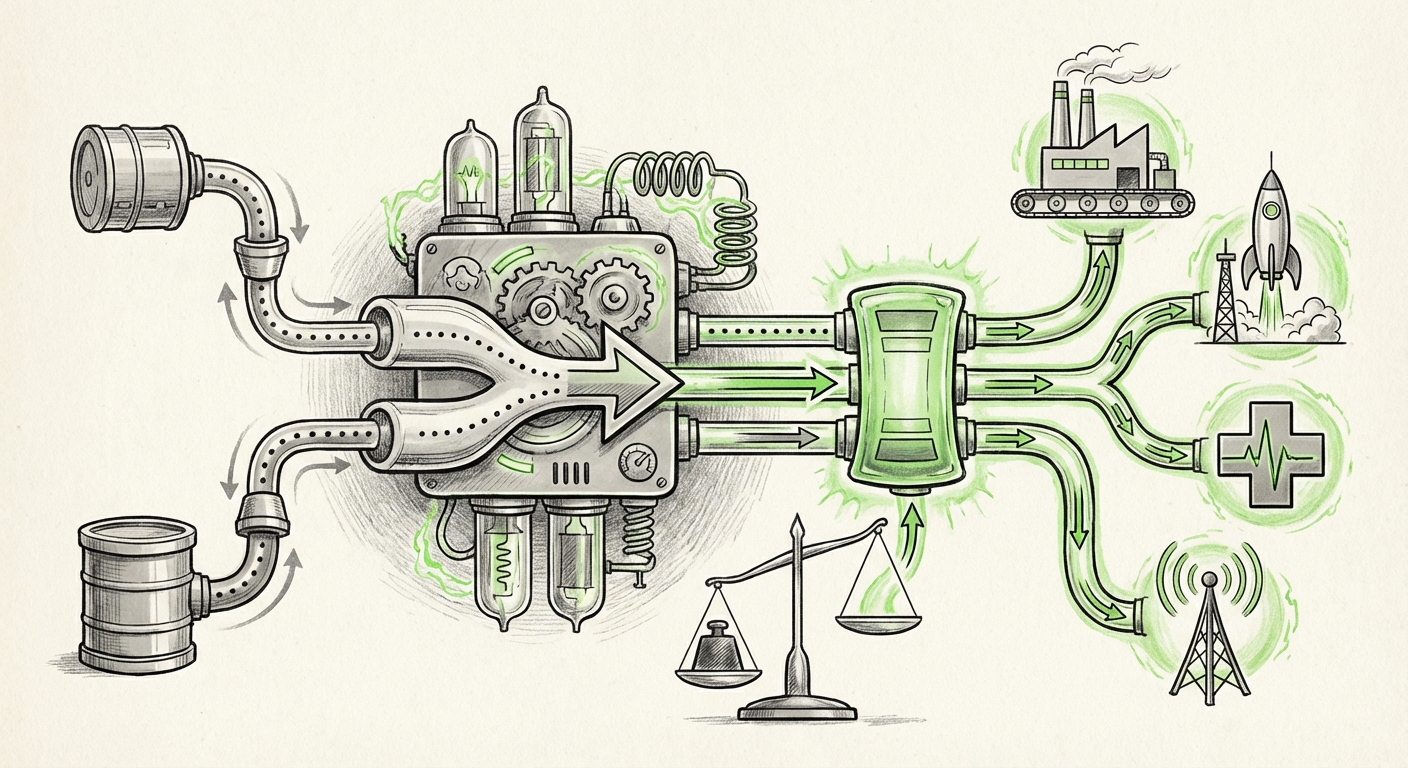
RTEB: The New Standard Set to Fix How We Measure AI Retrieval
Ask anyone who has built a working AI assistant why it gives bad answers, and you will usually hear the same thing: it could not find the right information. The model itself is often fine. The failure happens one step earlier, when the system goes looking through millions of documents, notes, product pages, or support tickets for the handful of passages that actually answer the question.
That step is called retrieval, and it has quietly become the most important, and least well measured, part of modern AI. On October 1, 2025, a new effort called RTEB arrived to change that. RTEB is a new standard for retrieval evaluation. Its goal is simple to state and hard to do: give everyone a fair, consistent, and honest way to test how well an AI system finds information.
That may sound like a technical detail. It is not. When evaluation gets better, everything downstream gets better, the models vendors sell, the systems companies buy, and the answers ordinary people rely on.
Why Retrieval Is the Quiet Engine Behind Modern AI
Most of the AI people use today is not just a model answering from memory. It is a system. The model is paired with a search layer. When you ask a question, the search layer pulls the most relevant pieces of text out of a database, and the model reads them before writing a reply.
This pattern, often called retrieval-augmented generation, is behind enterprise chatbots, customer support assistants, internal knowledge search, coding helpers, and the growing wave of AI agents that need to look things up before they act. It is also how companies keep models from making things up. If the right documents are retrieved, the model has evidence. If the wrong documents are retrieved, the model confidently repeats nonsense.
So retrieval quality is not a small tuning knob. It is the difference between a tool people trust and a tool people abandon. Yet for years, the way retrieval was judged lagged far behind its importance.
The Benchmark Problem Nobody Wanted to Talk About
Anyone shopping for a search or embedding model has run into the same wall. Leaderboards rank models with a single number. Higher looks better. But that number often tells you very little about how the model will behave in your world.
Three problems keep showing up:
- Mismatched tasks. A model that tops a leaderboard on general-purpose questions may stumble on messy, domain-specific material, legal filings, medical notes, product catalogs, code, or multilingual support logs.
- Test-set contamination. When benchmark data leaks into training data, scores go up without real improvement. The leaderboard looks better while real-world quality stays flat.
- The single-score illusion. One number hides the trade-offs that actually decide whether a system ships: latency, cost, storage, freshness, and fairness across languages and topics.
The result is a market where claims are hard to verify. Vendors pick the benchmark that flatters them. Buyers pick the model that wins the leaderboard and then discover it underperforms on their own data. Everyone spends money and time rebuilding the same internal tests.
What RTEB Is Trying to Fix
RTEB enters as a standard rather than a single scoreboard. That distinction matters. A standard sets the ground rules: what a retrieval task is, how results are scored, what must be disclosed, and how results should be compared. When those rules are shared, a number means something outside the lab that produced it.
The push behind RTEB rests on a few core ideas that are worth understanding, because they point to where AI evaluation is heading overall.
Measure retrieval on its own
End-to-end AI answers blend two very different skills: finding the right passage, and writing a good response from it. When a chatbot fails, teams burn weeks guessing which half broke. RTEB-style evaluation separates them. You test the search layer directly, so a bad answer traces back to a clear cause.
Cover the real world, not just the easy cases
A standard that only tests clean, well-written English documents will not survive contact with real data. Real corpora are messy, multilingual, jargon-heavy, and uneven in quality. Evaluation that reflects that mess tells you far more than a tidy academic set.
Make results comparable and reproducible
A benchmark is only useful if someone else can run it and get the same answer. Shared task definitions, shared scoring rules, and clear documentation turn evaluation from a marketing exercise into something closer to a measurement science.
Expose the trade-offs
Retrieval is an engineering decision, not a beauty contest. The best model for a low-latency phone assistant is rarely the best model for a nightly legal archive sweep. A good standard surfaces the full picture, accuracy alongside speed, cost, and resource use, so teams can choose instead of guess.
What This Means for the Future of AI
Model builders get a clearer target. When the yardstick is public and stable, teams can optimize for genuine gains instead of leaderboard tricks. That tends to shift investment toward the unglamorous work that actually improves products: better handling of long documents, mixed languages, and messy real-world text.
The retrieval stack becomes a first-class market. Vector databases, search engines, reranking tools, and embedding models have all been sold with fuzzy claims. A shared standard gives buyers a common language and gives good products a way to stand out without a marketing budget.
Agents get more reliable. The next wave of AI is agents that take actions, booking, filing, researching, coding. Every one of those actions depends on fetching the right context first. Better retrieval measurement is a direct upgrade to agent reliability, and reliability is the gate between a demo and a deployment.
Evaluation becomes continuous. Once measurement is standardized, it can be automated. Teams can re-run the same tests every time they change a model, an index, or a chunking strategy, and catch regressions before users do. Expect evaluation to become a permanent part of the AI pipeline, not a one-time bake-off.
Trust gets a paper trail. Regulators, auditors, and procurement teams increasingly ask a simple question: how do you know it works? A recognized standard gives an answer that is checkable rather than anecdotal.
What It Means for Businesses
For most organizations, the practical effect is a shift in how AI is bought and defended.
Vendor claims get easier to test. Instead of accepting a headline score, teams can ask for results on standard retrieval tasks, and then run their own evaluation on their own documents. The gap between the two is often the most revealing number in the room.
Budget conversations get sharper. Retrieval quality is directly tied to cost. A model that needs twice the compute to gain a point of accuracy may not be worth it. Standards that report trade-offs help leaders make that call with evidence instead of instinct.
Risk management improves. Most AI errors in production are retrieval errors wearing a disguise. When you can measure retrieval separately, you can also monitor it separately, catching drift when a product catalog changes, a policy is updated, or a new language is added.
Internal teams stop duplicating work. Many companies have quietly built their own evaluation harnesses. A shared standard lets them adopt proven methods and spend their energy on the parts that are genuinely unique to their business.
What It Means for Society
Retrieval decides what information an AI system can see and, by extension, what it tells people. When evaluation is weak, failures are invisible until they cause harm. When evaluation is strong, problems show up in a test suite instead of in a customer's hands.
That matters for accountability. If an AI assistant gives wrong medical guidance or misstates a legal requirement, the question of whether the system was properly tested becomes central. A public, shared standard makes that question answerable. It also helps smaller players, startups, public institutions, researchers in under-resourced settings, compete on quality rather than on access to private testing data.
There is a caution here too. No benchmark is neutral. The tasks a standard chooses to include decide what gets optimized, and what gets ignored. The retrieval challenges that matter most to non-English speakers, low-resource domains, and accessibility use cases need to be inside the standard, not bolted on later.
An Actionable Playbook
If you build or buy AI systems, here is where to start.
- Separate retrieval from generation in your own testing. Build a small set of real questions with known correct source documents. Score the search layer on its own before you blame the model.
- Test on your data, not just public sets. Public benchmarks tell you where to start. A few hundred labeled examples from your own corpus tell you what to ship.
- Track more than accuracy. Log latency, cost per query, freshness, and performance across languages and document types.
- Ask vendors for standard-aligned results. A vendor that can produce retrieval-specific evidence is usually a vendor that has thought about retrieval.
- Re-run your evaluation on a schedule. Tie it to model upgrades, index rebuilds, and content changes so regressions surface early.
- Guard against contamination. Keep an internal holdout set that never touches training or tuning, and rotate it periodically.
The Road Ahead
A standard is only as strong as its adoption. The next phase for RTEB is the harder one: getting model providers, database vendors, and enterprise teams to run the same tests and publish comparable results. History suggests that once a credible standard exists, pressure builds quickly, buyers start asking for it, and vendors that ignore it look like they have something to hide.
Watch for three signals. First, whether major model and search providers publish RTEB-aligned results. Second, whether procurement teams start writing it into requirements. Third, whether the standard keeps expanding into the messy, multilingual, domain-specific territory where real AI systems live. If all three happen, retrieval evaluation stops being a marketing footnote and becomes infrastructure.
Final Thoughts
The AI conversation is dominated by models, bigger, faster, smarter. But the systems people actually use are only as good as the information they can find. RTEB is a bet that measuring that step properly, in public and on shared terms, will make the whole stack better: more honest benchmarks, better purchasing decisions, more reliable agents, and AI that earns trust instead of asking for it.
For anyone building with AI today, the takeaway is not to wait for the standard to mature. It is to start measuring retrieval like it matters, because it already does.